Incidents & Services
Alerts are symptoms. Services tell you which system is hurting, and incidents are how the team coordinates the fix. This guide covers the layer above the alert queue: the service catalog, incident response, cron monitoring, and planned maintenance.
- Alerts flowing in, per Getting started.
- Admin access for creating services and maintenance windows; anyone can declare an incident from an alert.
-
Model your systems in the services catalog
Services are the systems you run — APIs, frontends, databases, queues. Each service has a health state (OK, degraded, or down) that rolls up from its alerts. Create one service per system you page for, link incoming alerts to it, and choose an Alert icon from the catalog (or leave Generic). The selected application icon appears beside linked alerts in both the console and mobile app.
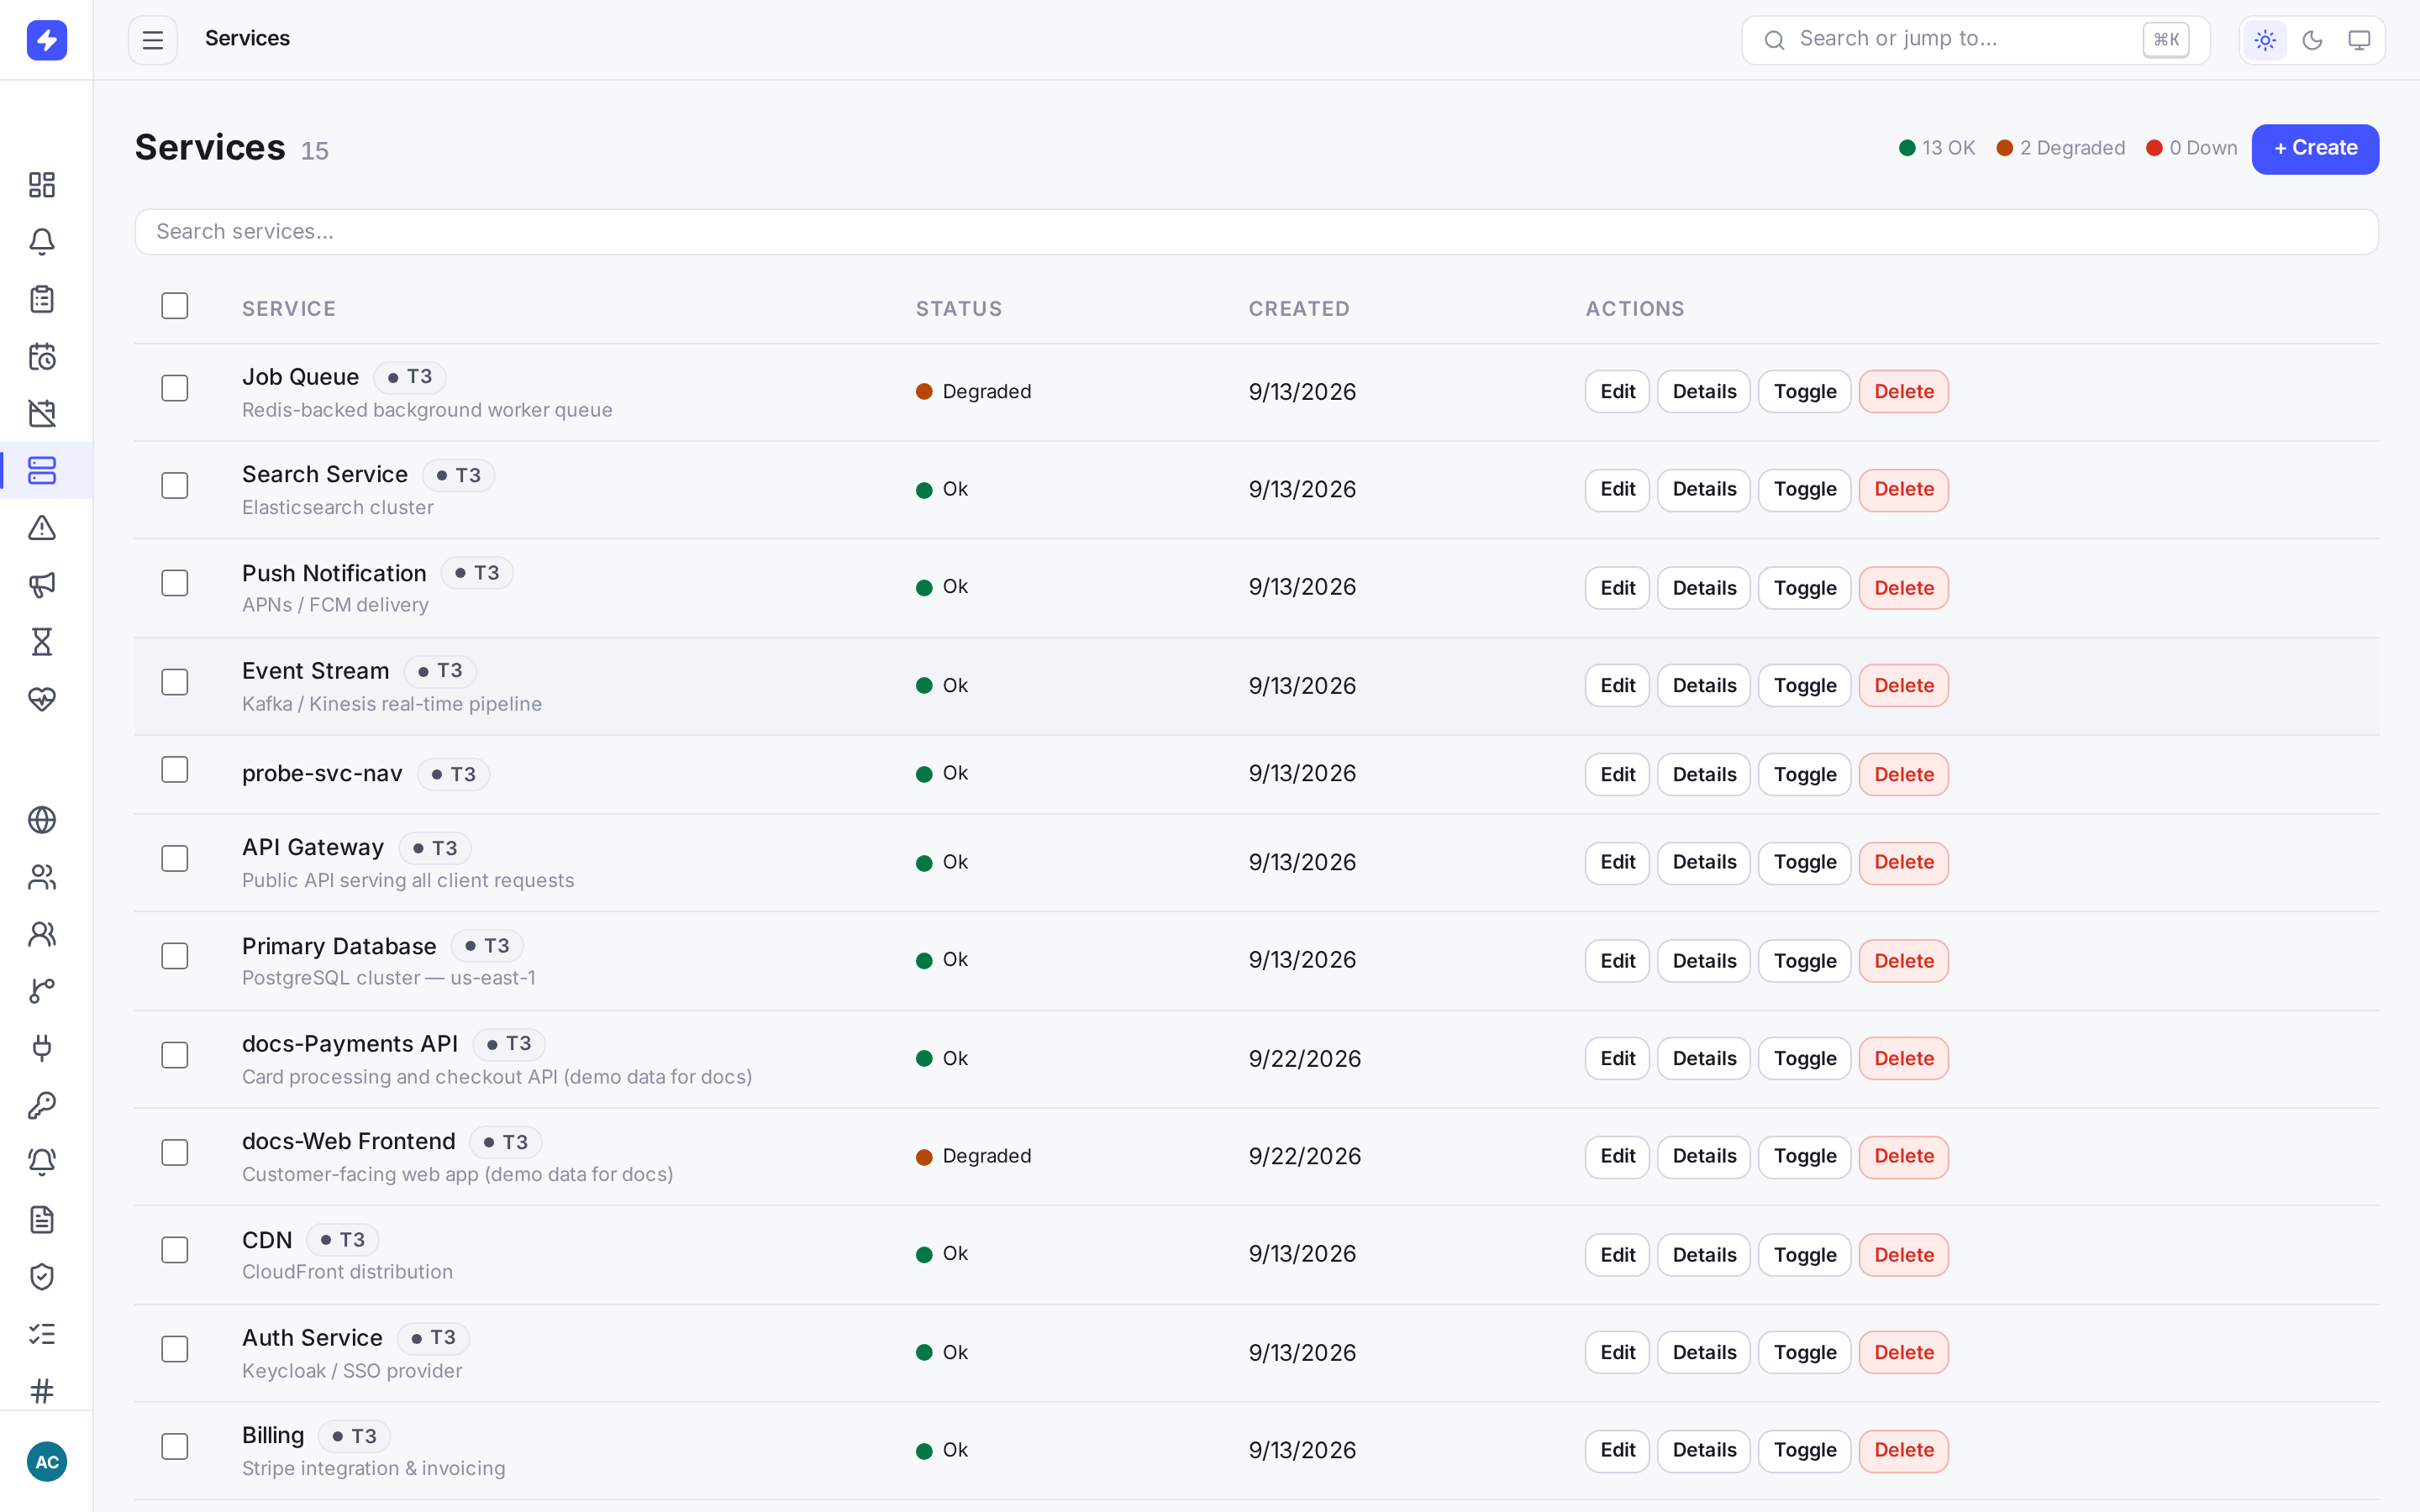
Services carry ownership, health, and an alert icon that makes linked alerts recognizable at a glance. 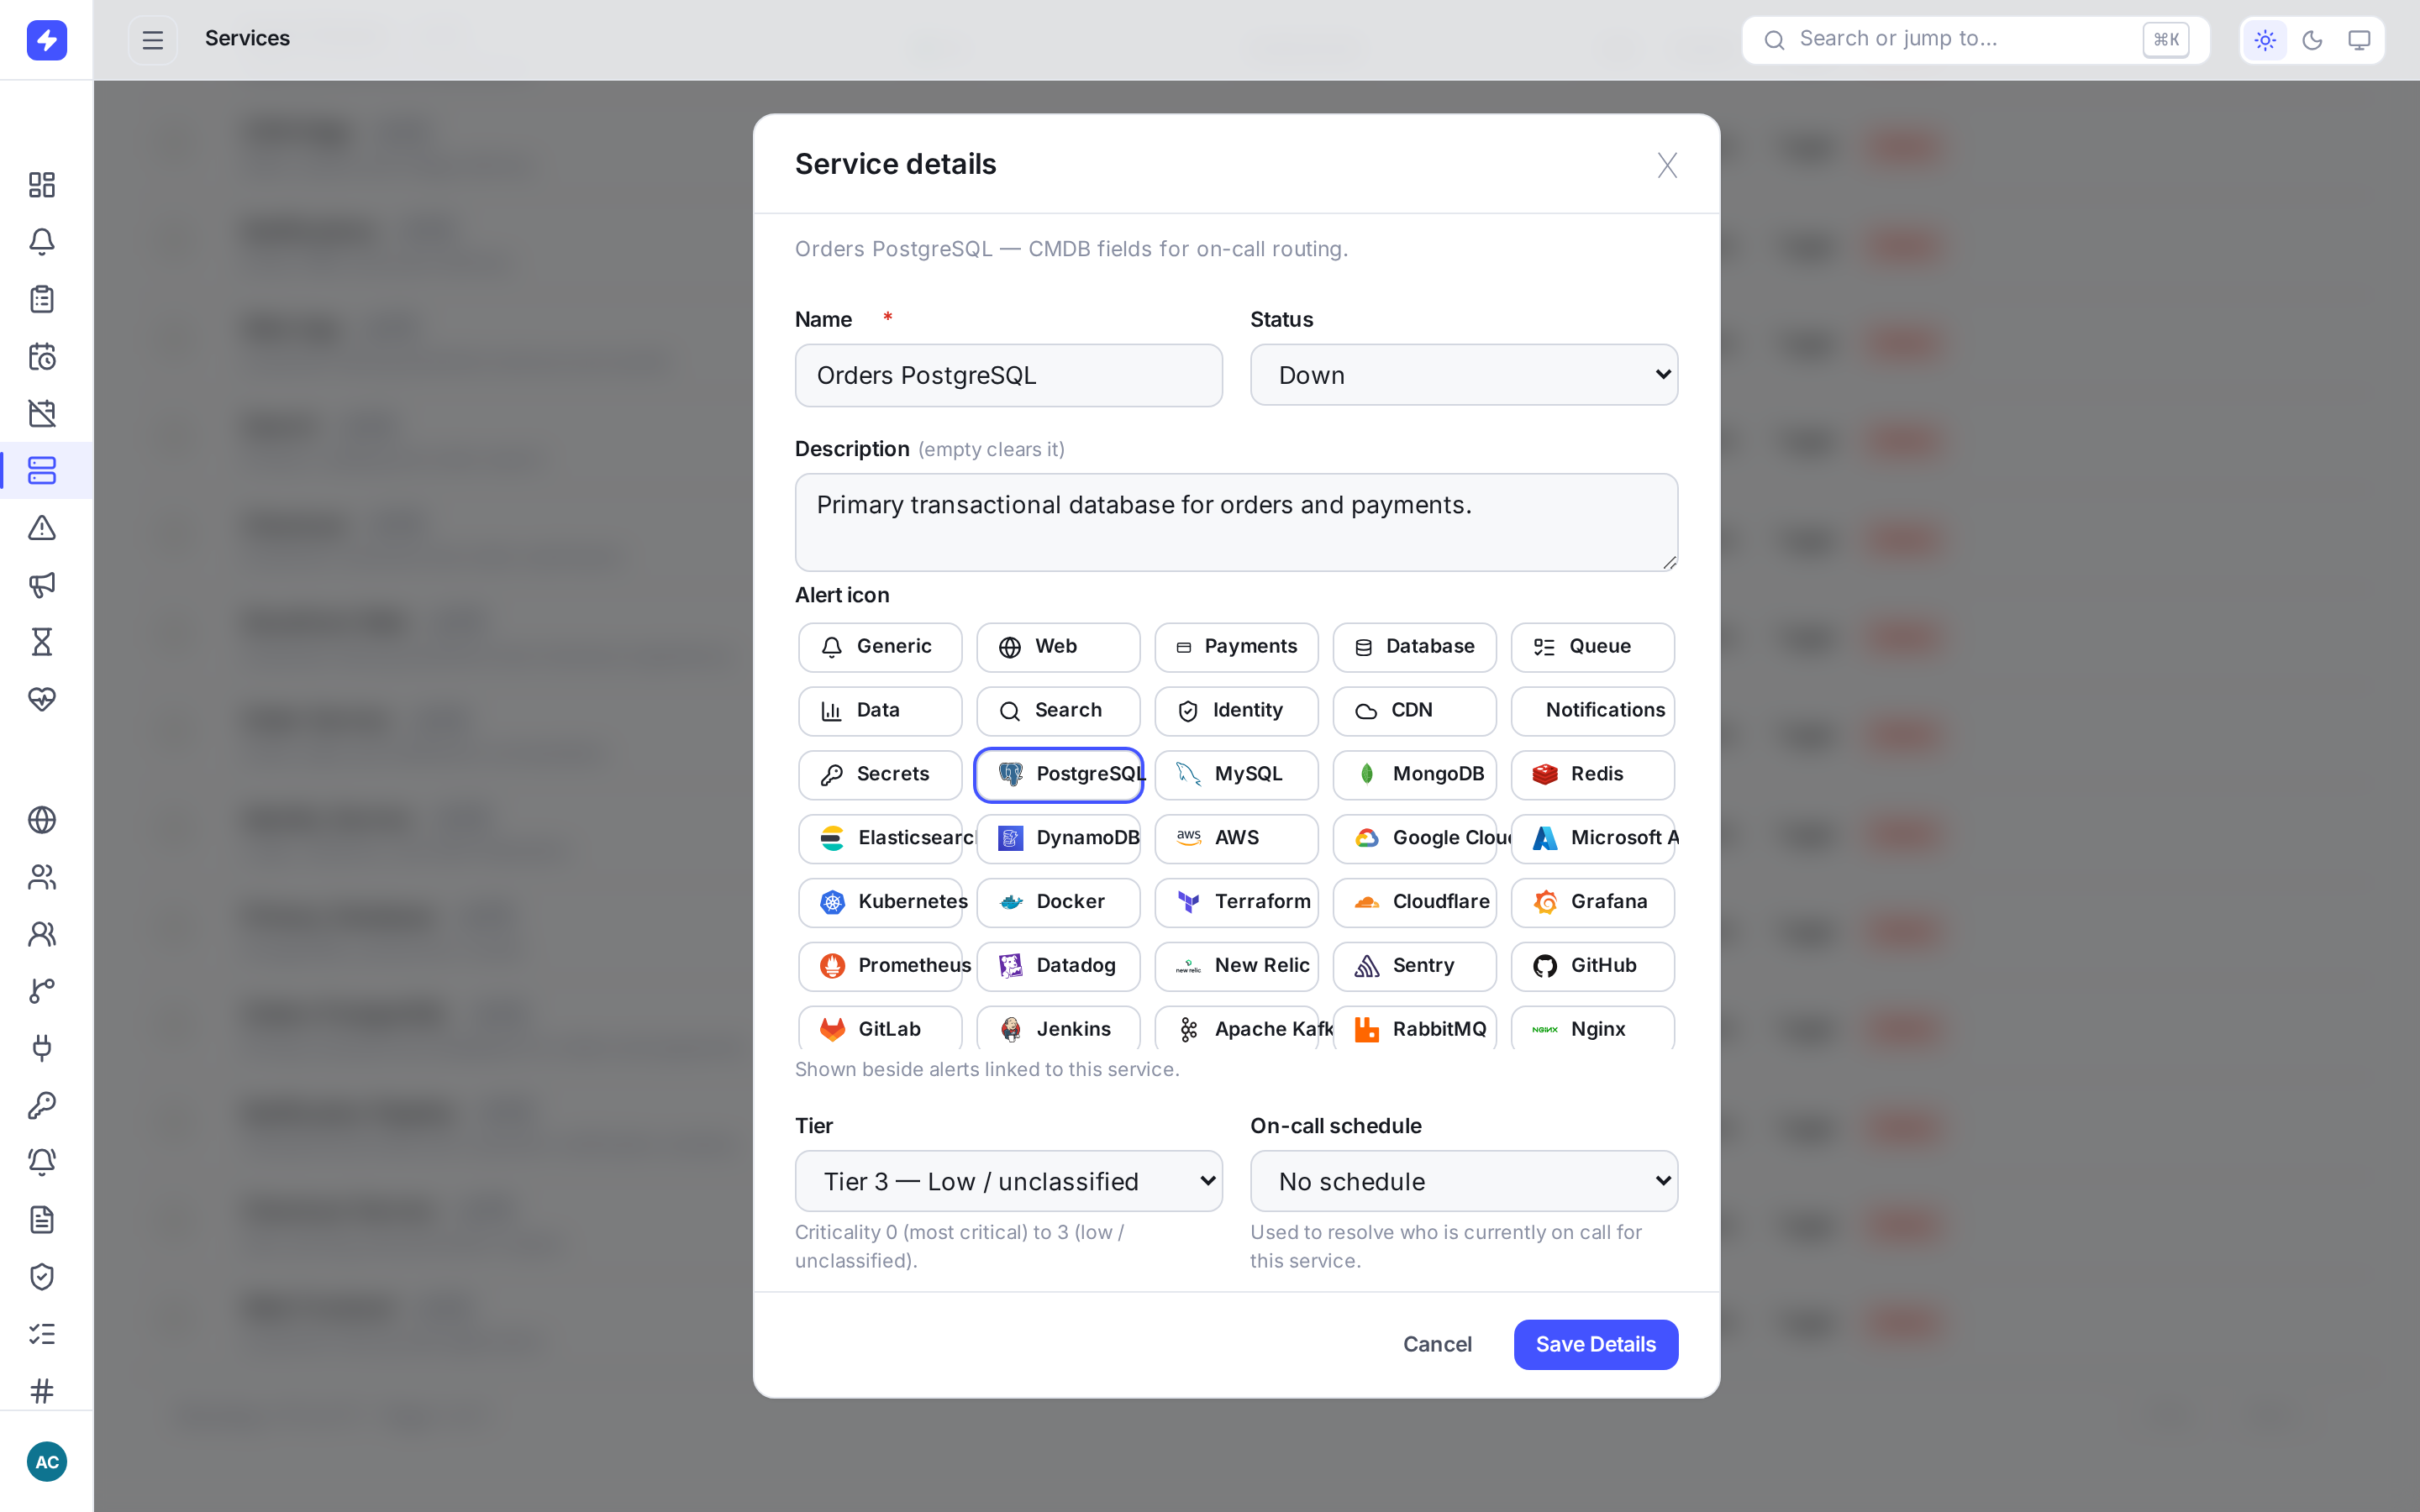
Set the icon once on the service. Native alerts link it with serviceId; mapped monitoring alerts can inherit it from the integration's Default service.The icon belongs to the service, not the alert payloadOpsPing does not accept arbitrary icon URLs from incoming alerts. That keeps the queue consistent and prevents untrusted image content. Choose an icon from the service catalog, then link the alert to that service. For Grafana or Alertmanager, see the containerized end-to-end example.
-
Declare an incident from an alert
When an alert is bigger than one person — customer-facing, multi-system, or just unclear — promote it. The Declare incident action on alert detail creates an incident with that alert linked. You can also choose Create Incident on the Incidents page and complete the creation dialog.
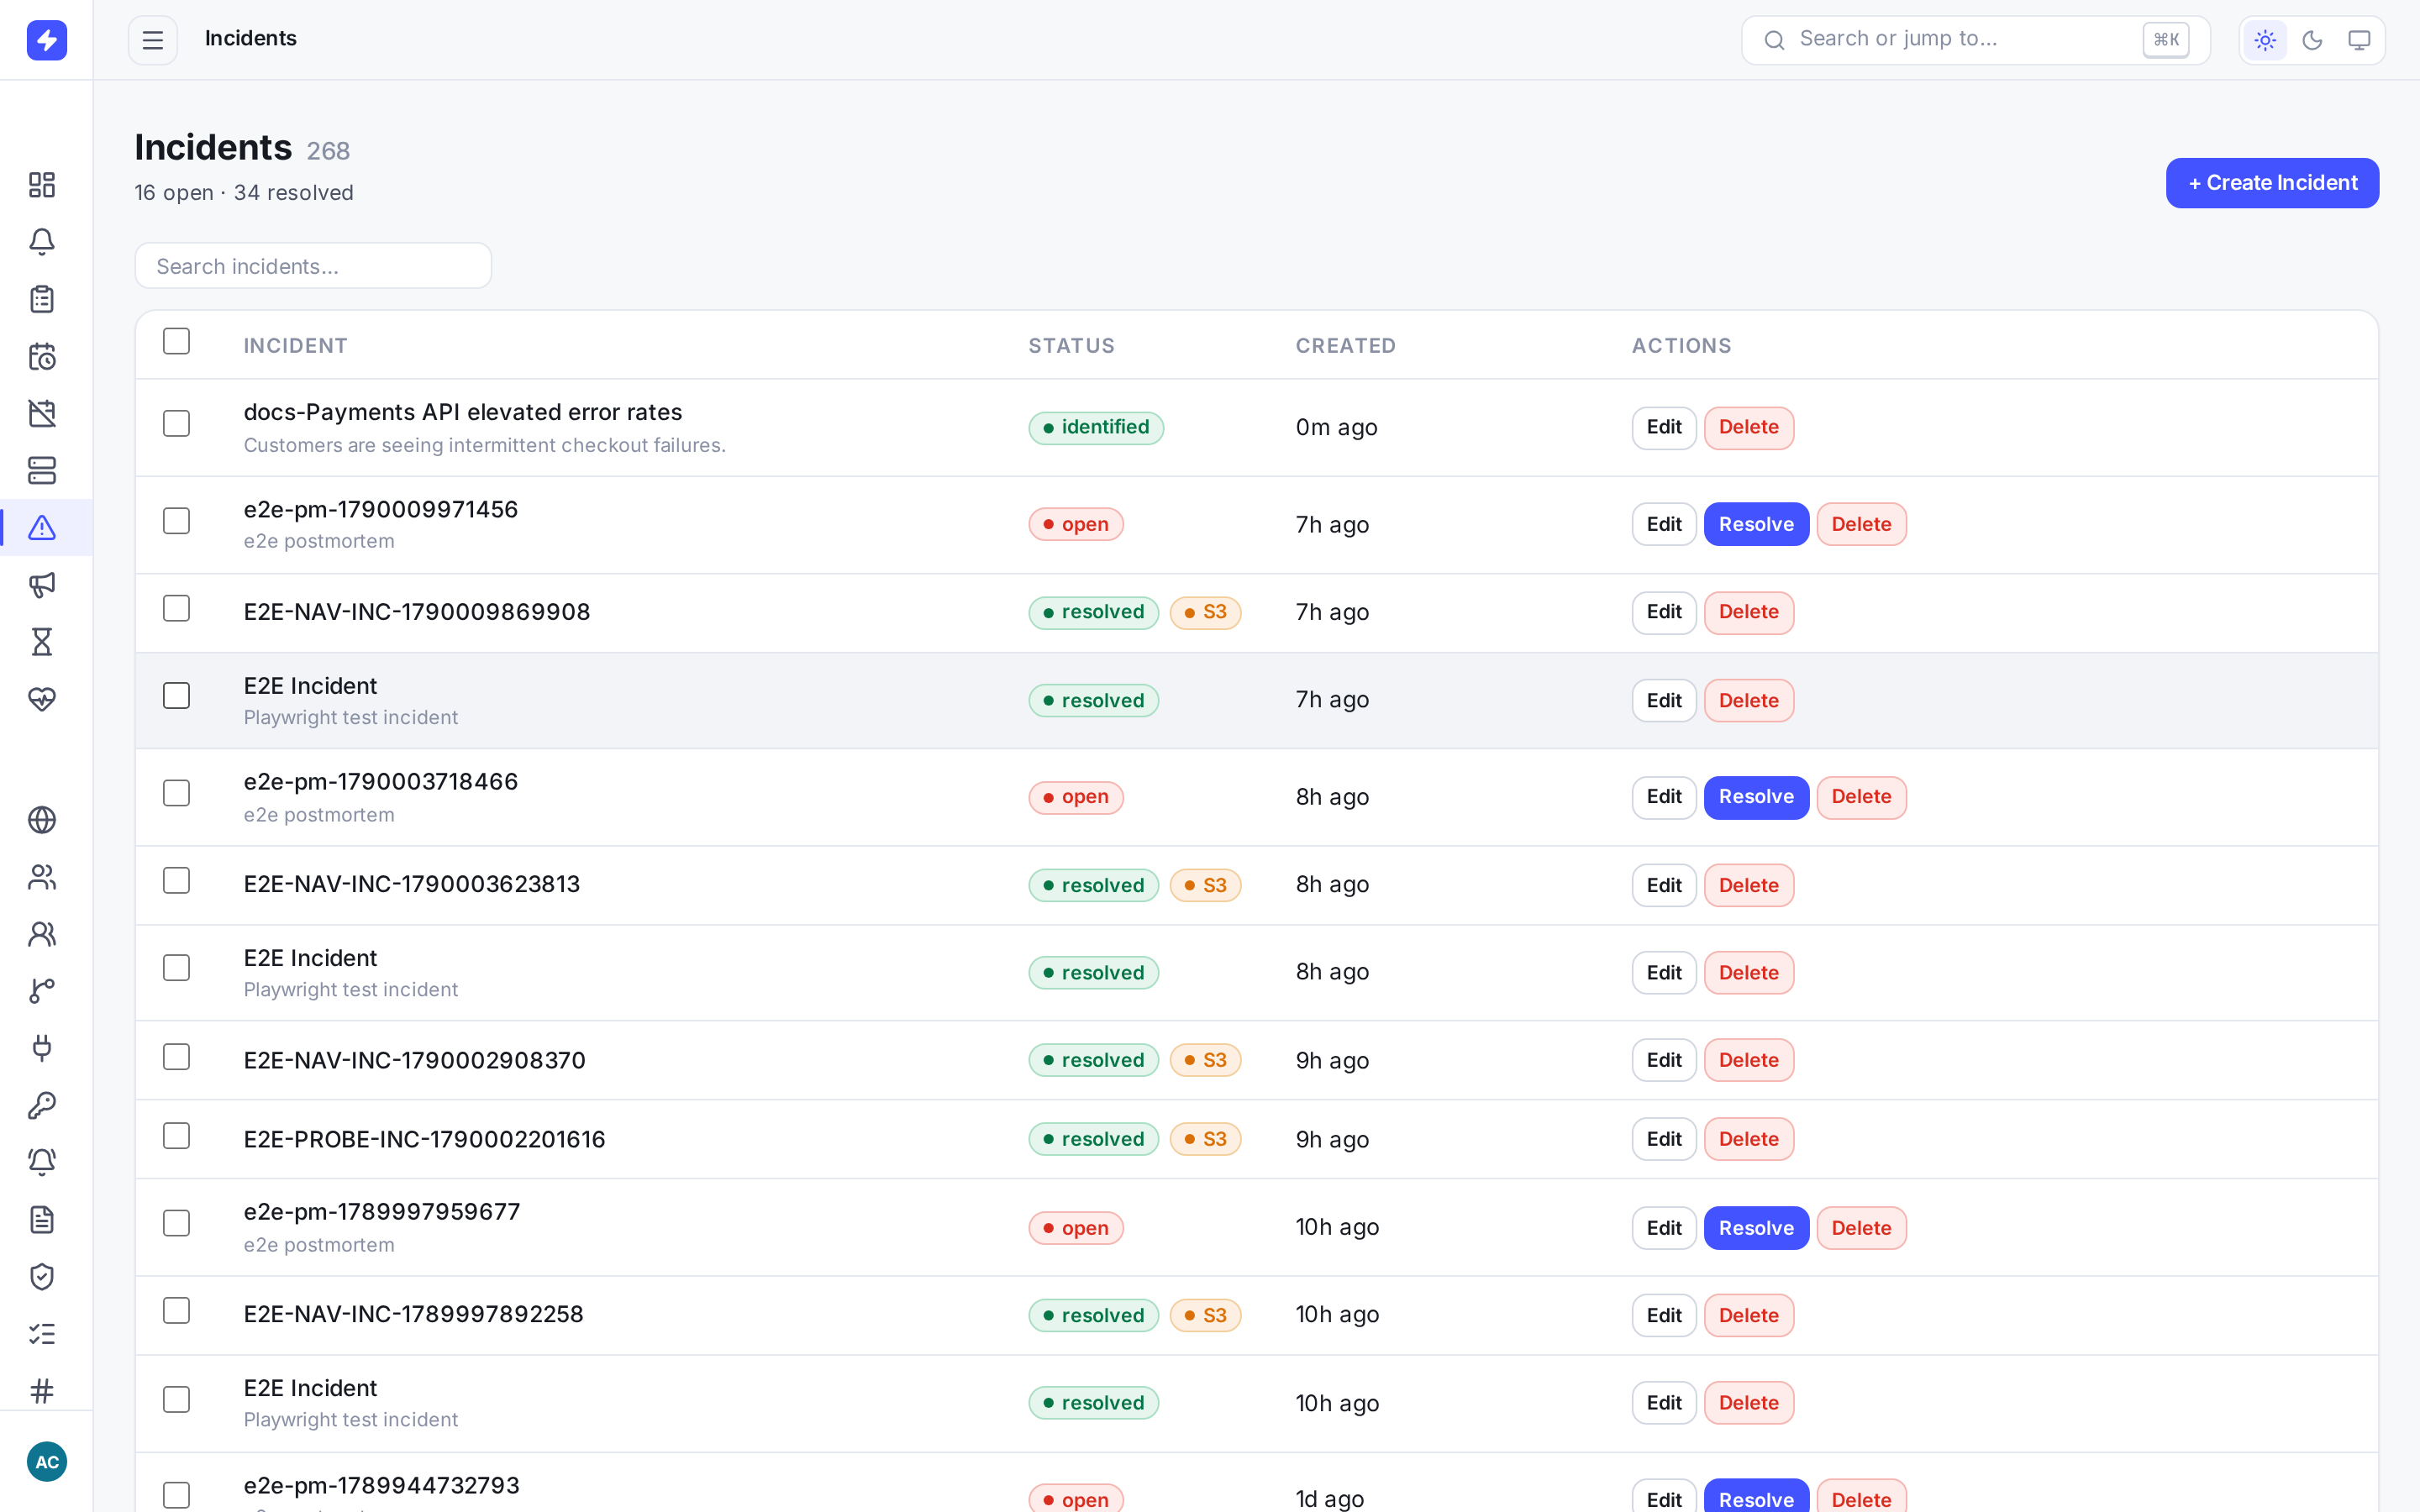
The incidents list shows open and resolved incidents. Create one from the page or declare it from an alert. TipDeclare early. An incident costs nothing but a name; an hour of three people independently investigating the same P1 costs real sleep. The rule of thumb: if you're about to message a second person about an alert, it's an incident.
-
Resolve the incident and publish deliberate status updates
Incident detail is the shared responder picture: overview, tags, responders, impacted services, linked alerts, and lifecycle markers. Use Resolve to resolve the incident and close its linked alerts. In the Status page section, publish customer-facing updates labelled investigating, identified, monitoring, or resolved. Published update text is public and can email subscribers; keep private responder notes out of it.
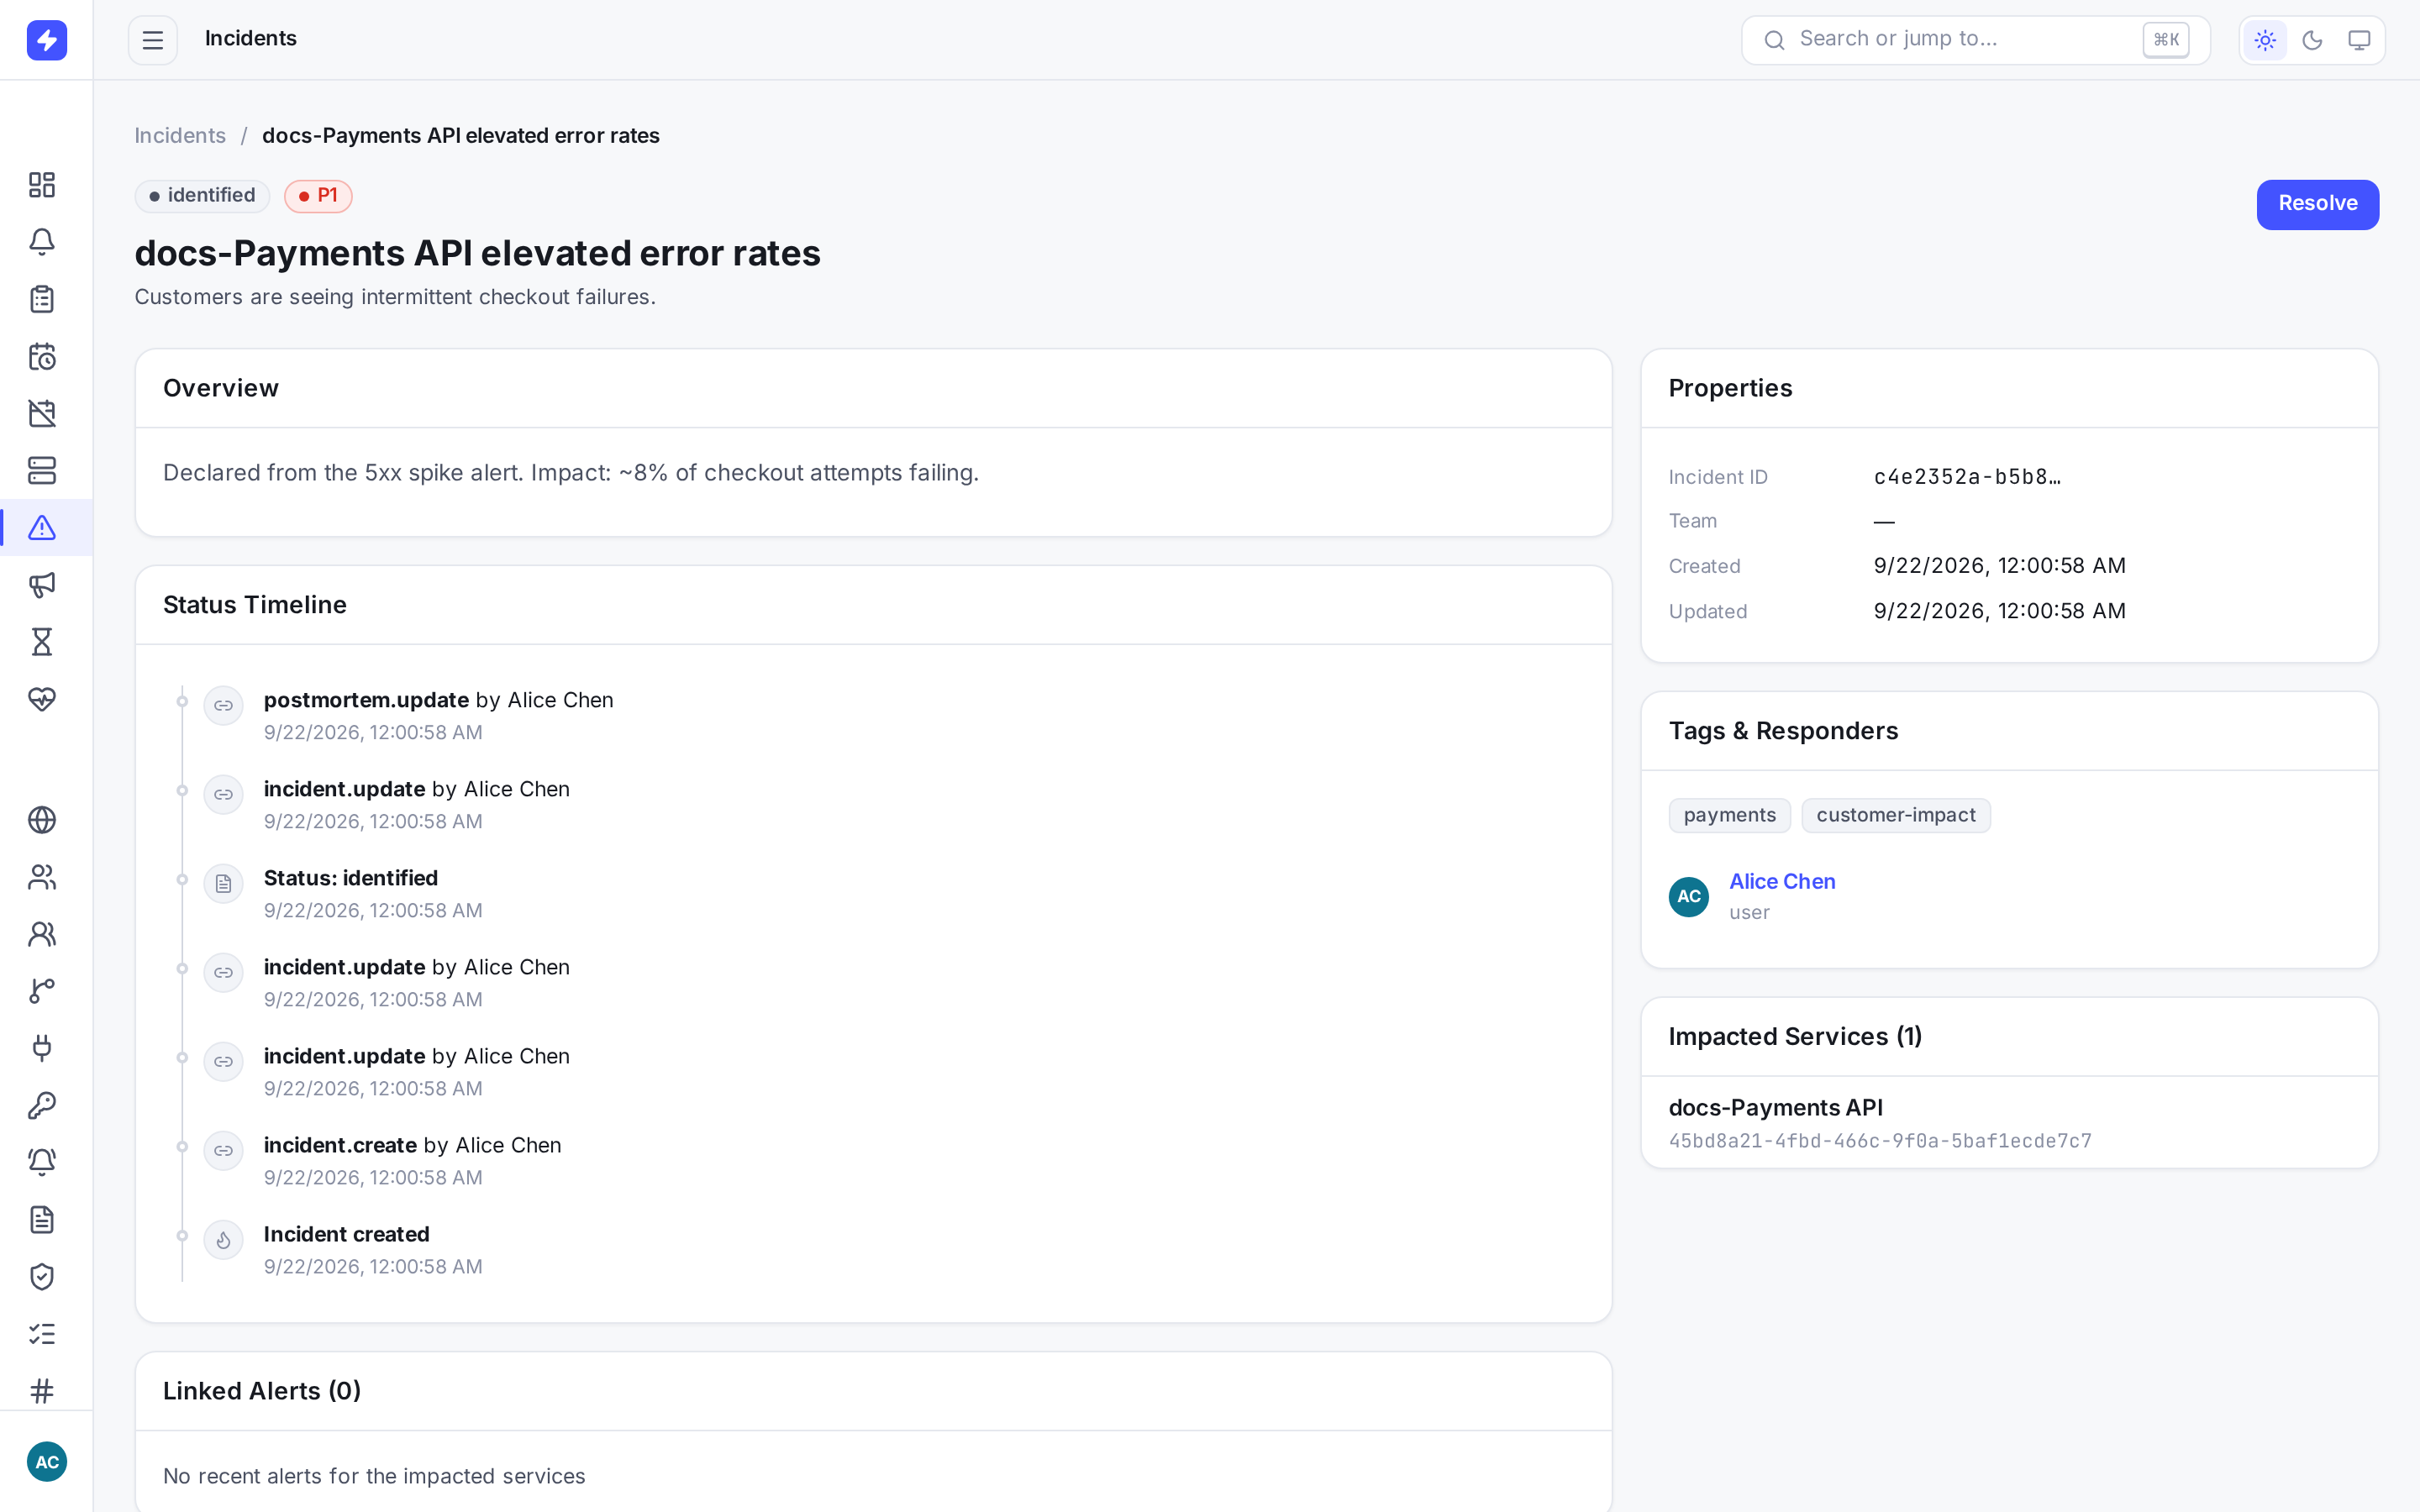
Incident detail separates responder lifecycle actions from customer-facing Status page updates. NoteThe Status Timeline records lifecycle markers. The Status updates section records messages you deliberately publish to the status page.
-
Monitor cron jobs with heartbeats
Some failures are silent: the nightly ETL that simply doesn't run raises no alert. Heartbeats invert the model — your job pings OpsPing when it finishes, and if no ping arrives within the expected interval, OpsPing raises an alert for you. Create a heartbeat per scheduled job, then have the job hit the heartbeat URL on success.
curl -X POST https://api.opsping.com/v2/heartbeats/nightly-etl/ping \
  -H "Authorization: OpsPingKey YOUR_API_KEY"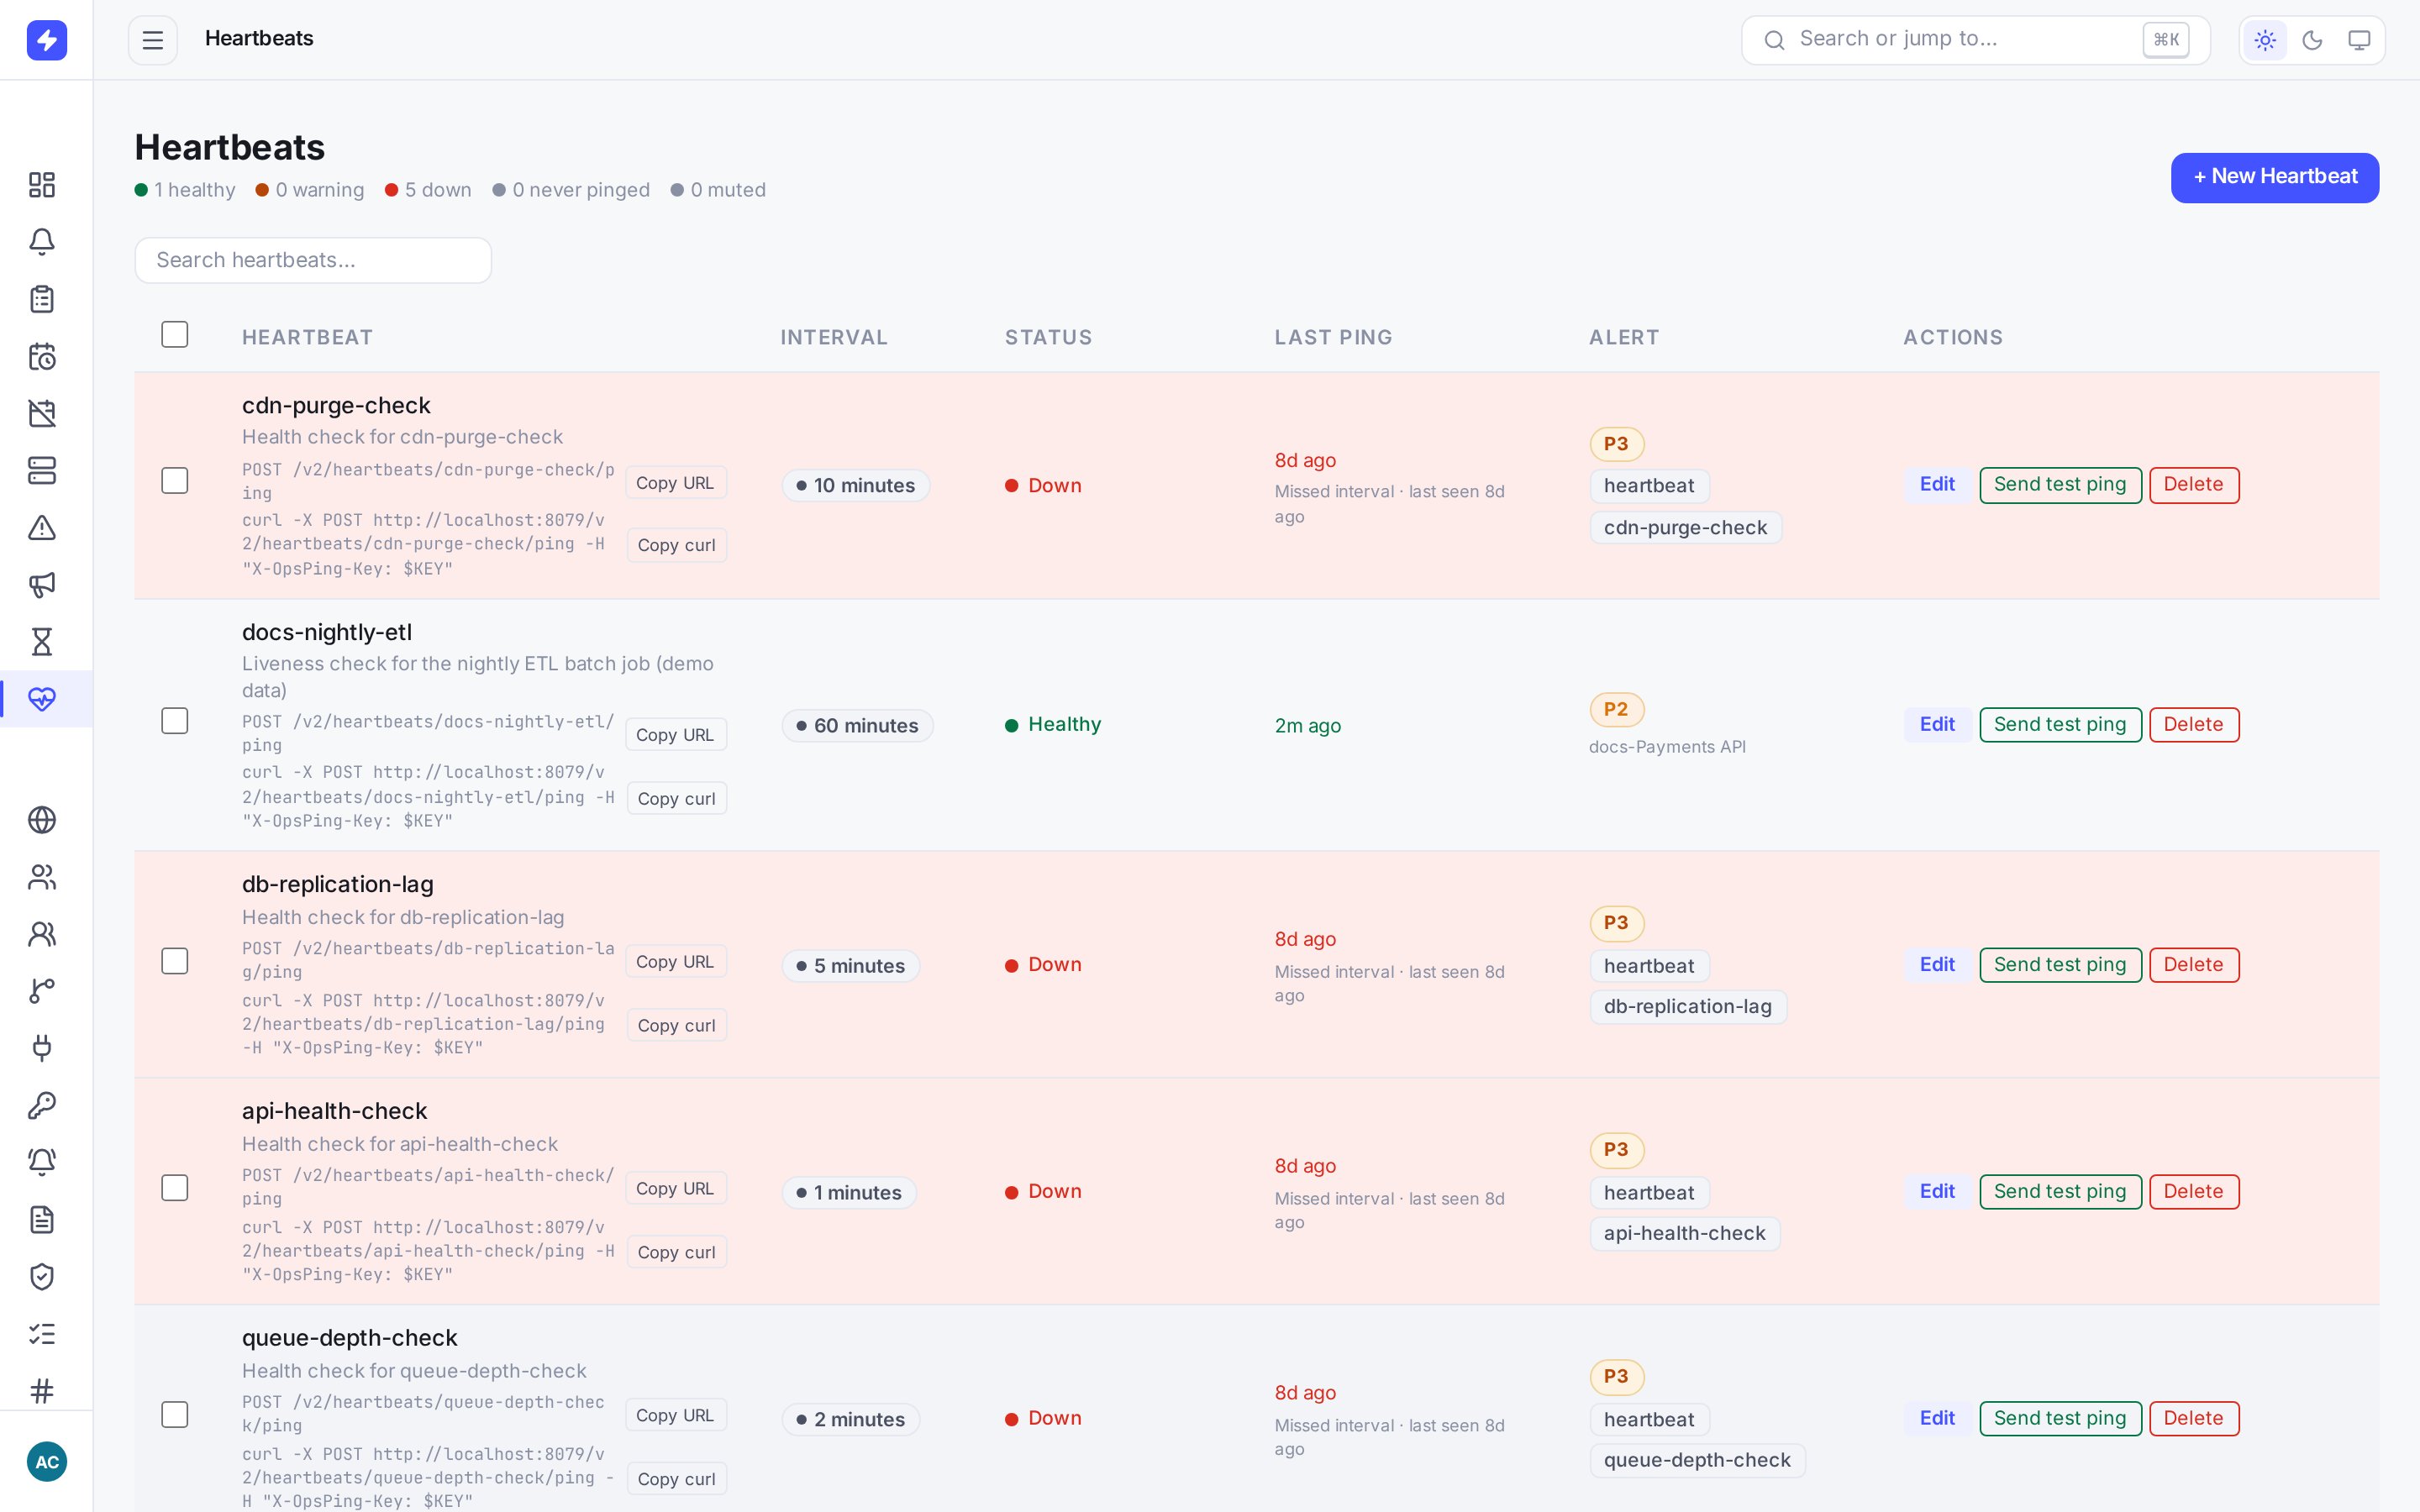
Heartbeats monitor cron jobs and batch processes: if the nightly orders export stops pinging, OpsPing raises an alert. TipPut the ping at the end of the job, after the work succeeded — not in a wrapper that fires when the script starts. A heartbeat that pings on launch tells you the job started, not that it finished.
-
Silence planned work with maintenance windows
A maintenance window suppresses the initial paging path for matching alerts during planned work while retaining each alert and a suppression activity entry. Slack and outbound webhooks can already have received the alert, and stored maintenance alerts are not automatically excluded from response-time reports. The page groups windows into upcoming, active, and expired.
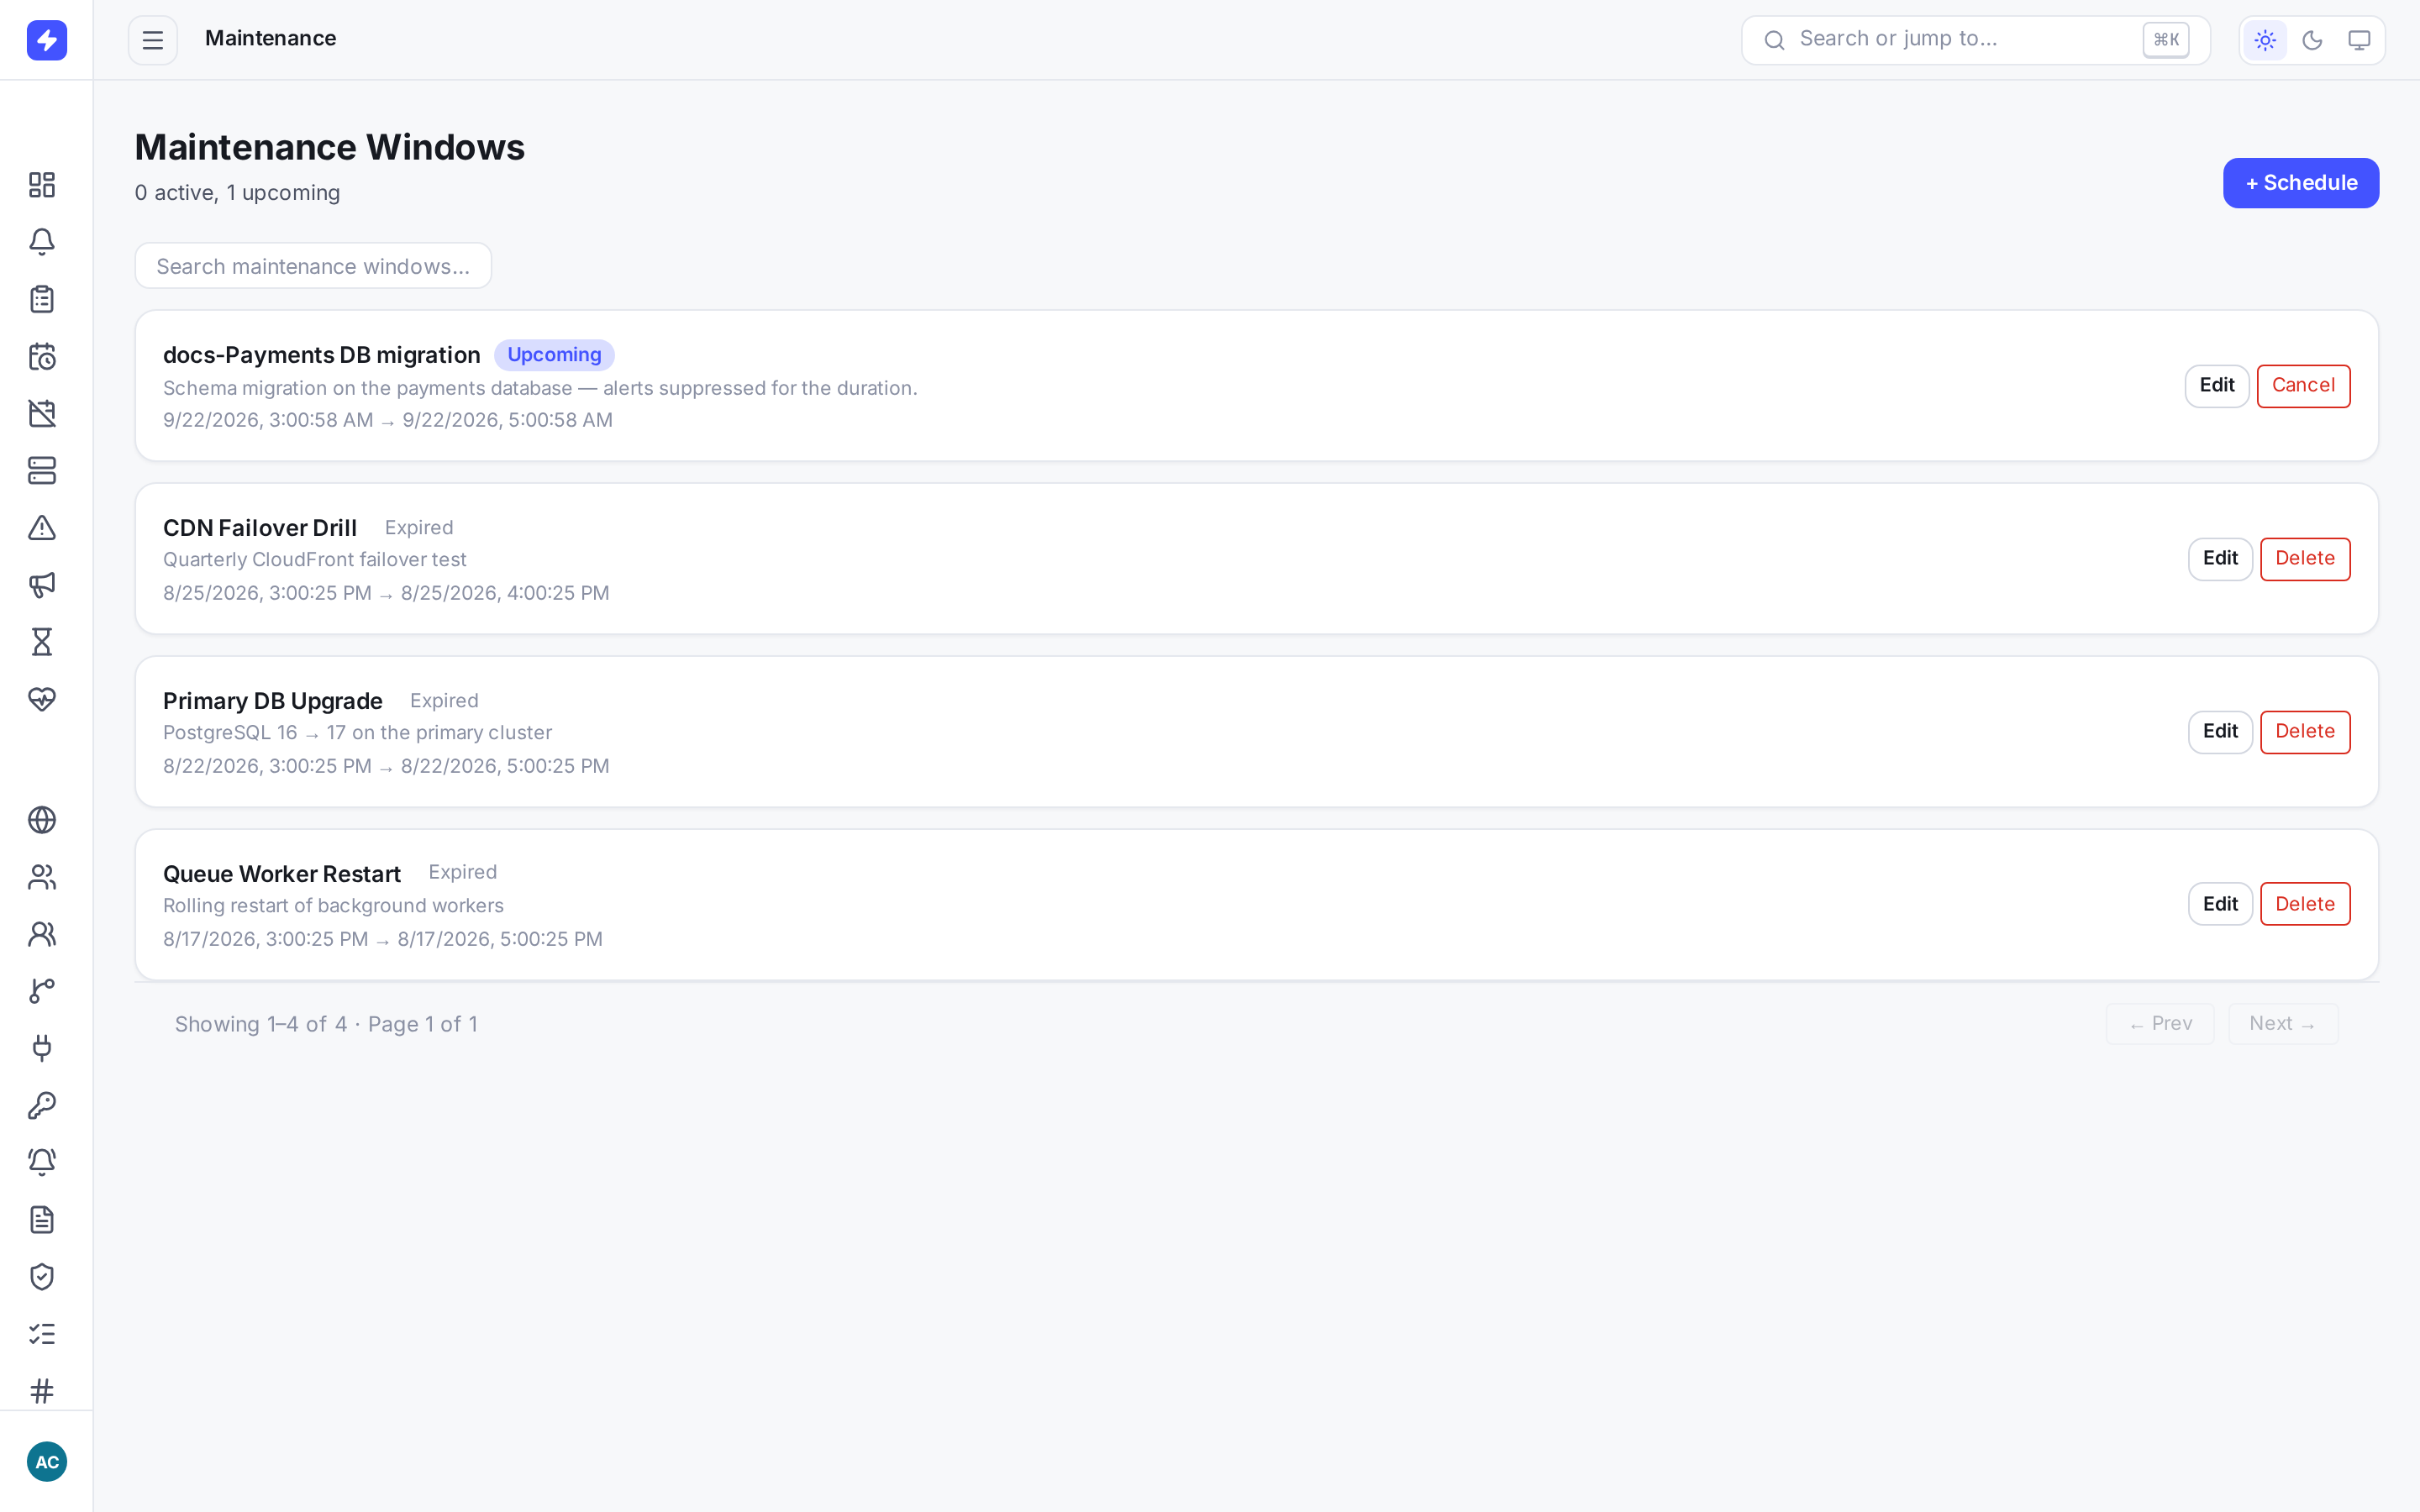
Maintenance windows suppress paging for scoped work; they do not hide the alert record. WarningMaintenance windows suppress real problems too. Scope them tightly — one service, the actual deploy window — rather than a whole team for a whole evening. "We were in maintenance" is not a good answer to "why did nobody see the outage."
-
Watch it all from the mobile health tab
The mobile Health tab rolls incidents and services into one view: active incidents, service status cards, and shortcuts to resolve an incident or declare a new one. It's the pocket answer to "is anything on fire right now?"
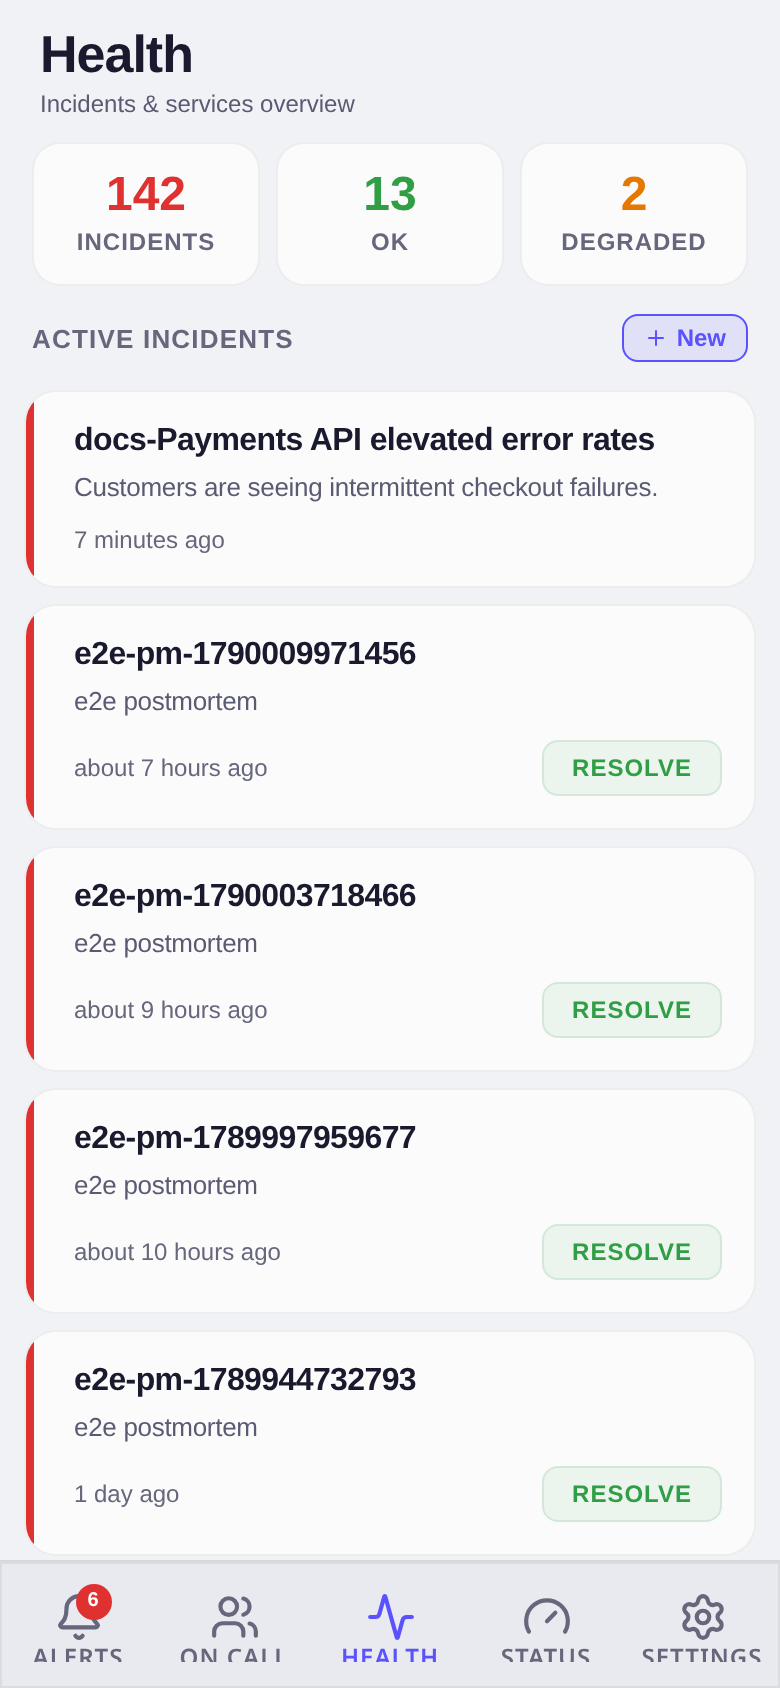
The health tab summarizes active incidents and service status, with shortcuts to resolve incidents or declare a new one. -
Attach runbook context with service fields
A service is more than a name and health state. Give it a tier, alert icon, on-call schedule, owners, runbook URL, and Slack channel. Alert detail then shows service context and the console/mobile queues show the chosen icon; OpsPing can also suggest service owners as responders.
TipWith Slack delivery configured, a service's channel can receive an additional card for alerts linked to that service. See Slack ChatOps.
-
Generate a postmortem when it's resolved
When the incident is resolved, generate a postmortem from its timeline, status updates, responders, and linked alerts. Save editorial changes before refreshing the generated timeline; saved summary, root-cause, and template-section edits survive regeneration. Export to Markdown or PDF for review. See Postmortems.